
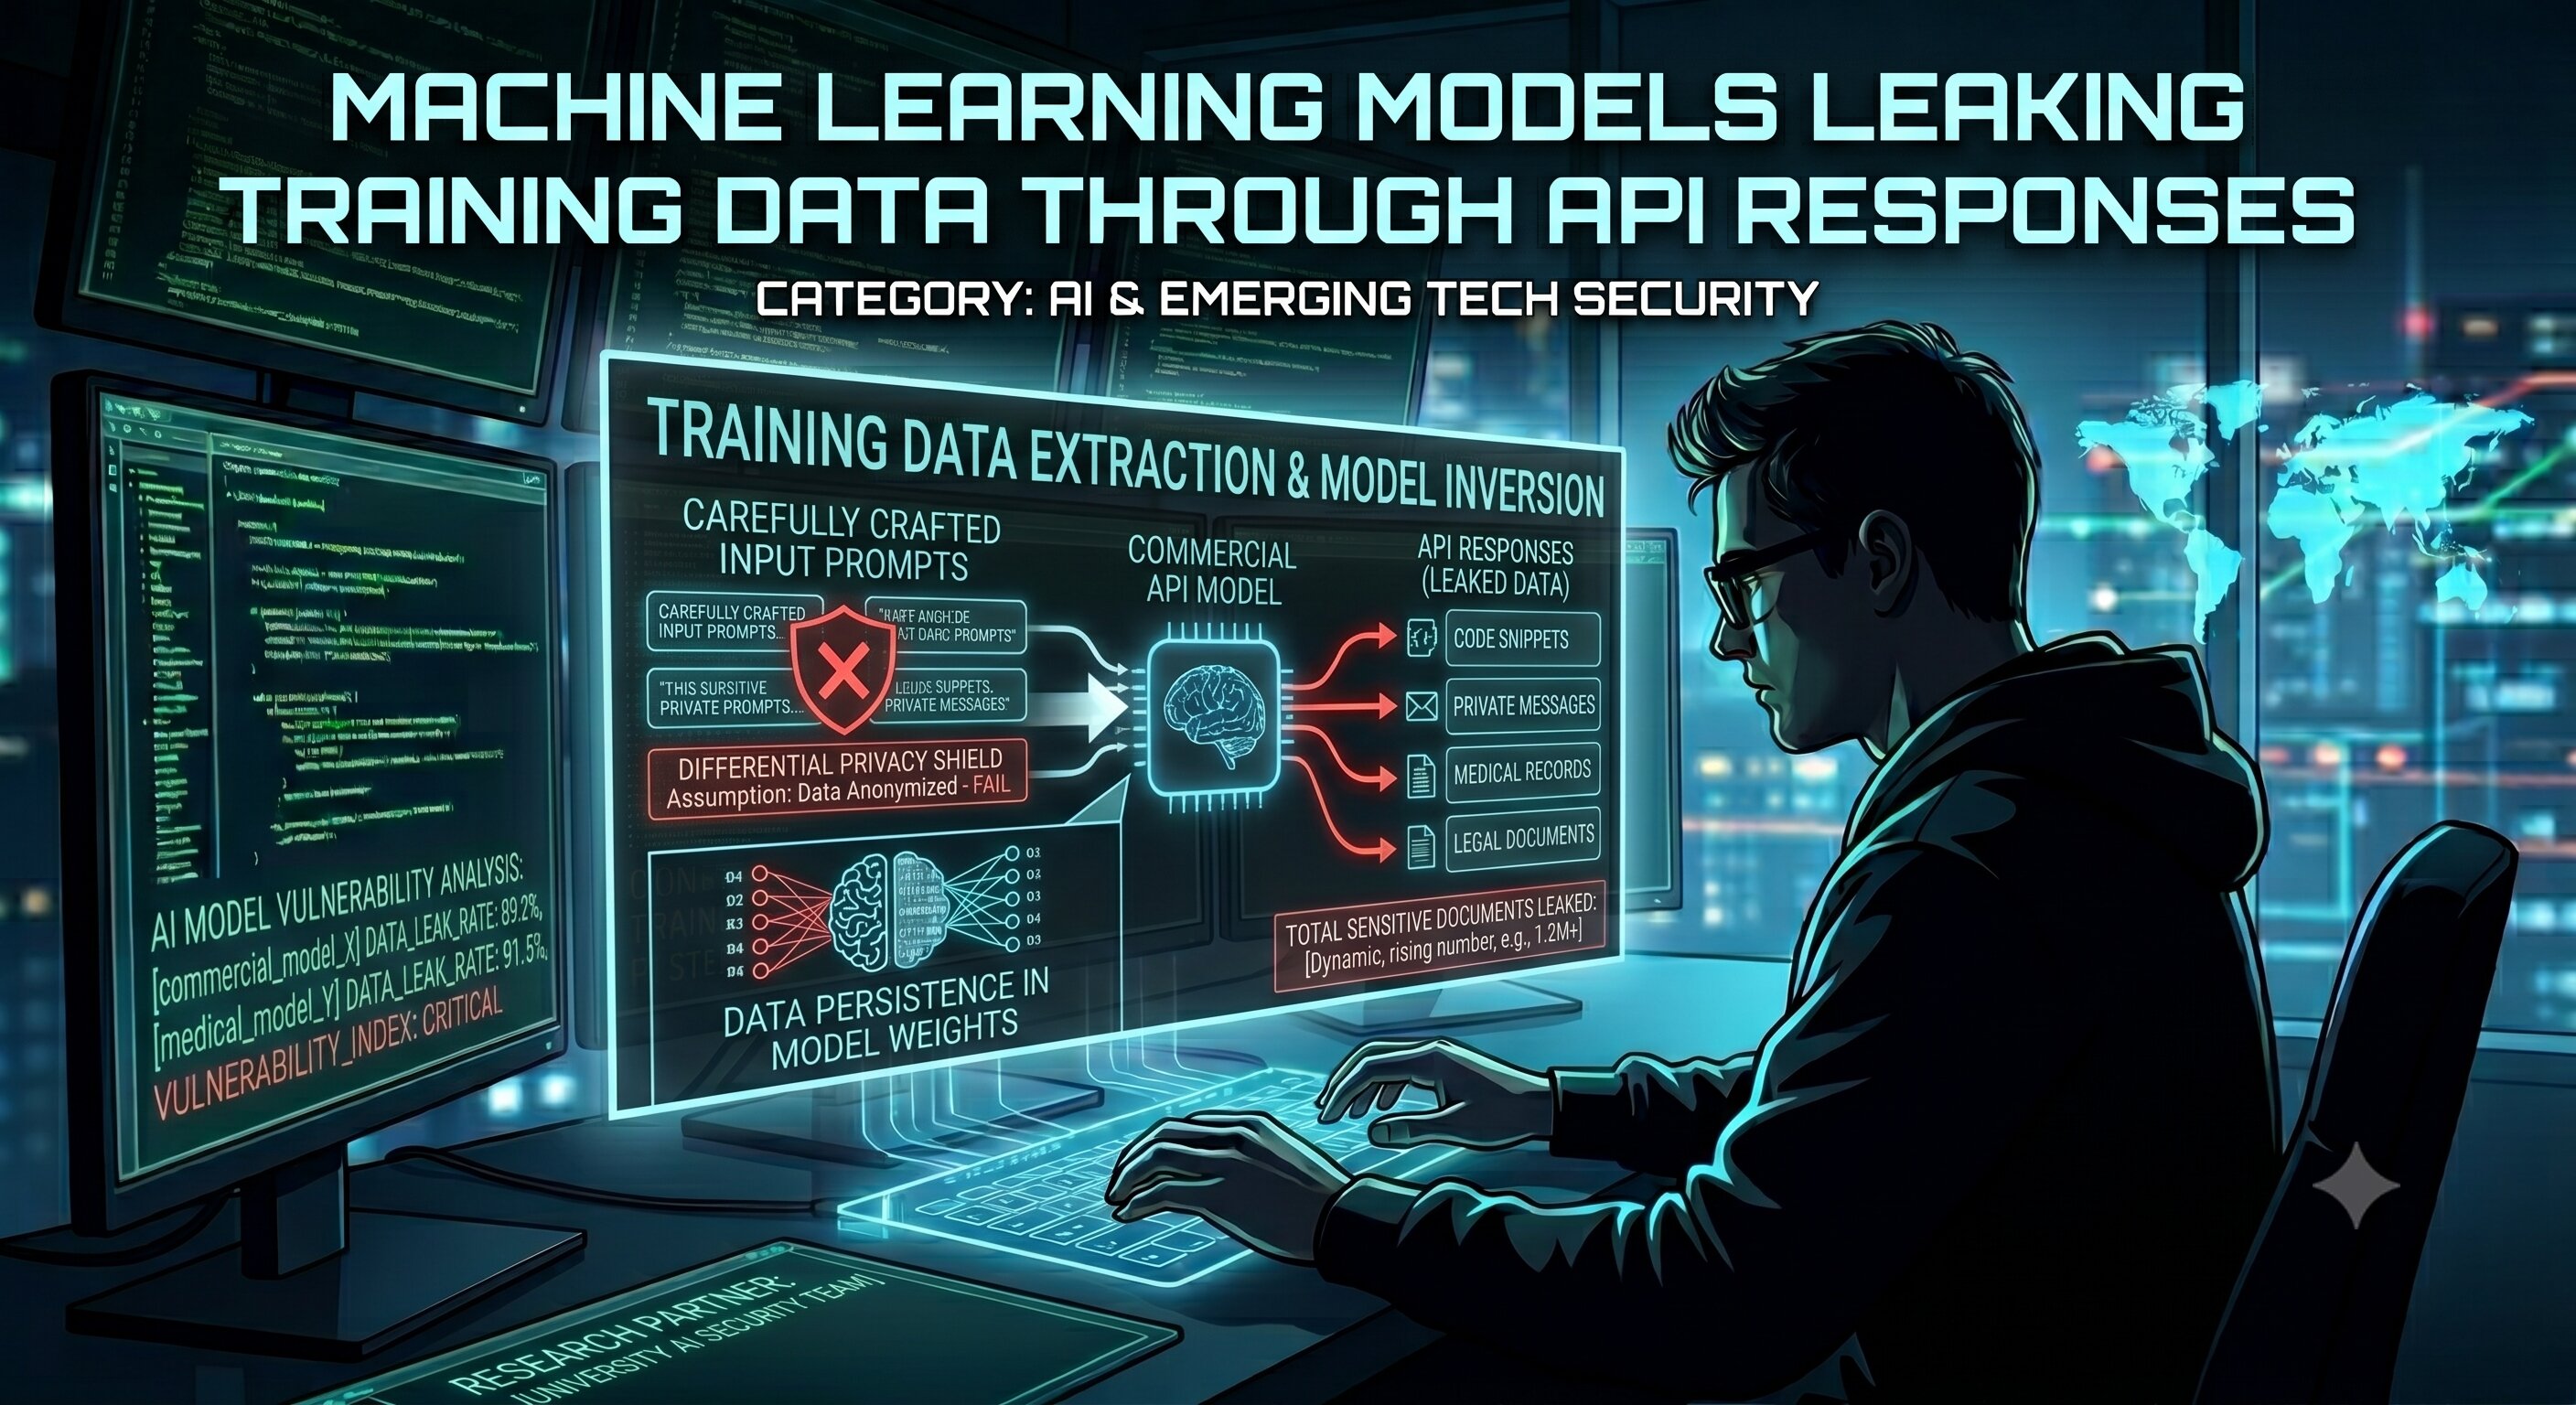
Machine Learning
Models Leaking Training Data Through API Responses
Category:
AI & Emerging Tech Security
Research
published by a team of AI security specialists has demonstrated that machine
learning models deployed via commercial APIs can be induced to leak sensitive
information from their training datasets through carefully crafted input
prompts. The phenomenon, known as training data extraction or model inversion,
represents a significant privacy risk for organizations whose data has been
used — knowingly or unknowingly — to train commercial AI systems.
Using a
technique called membership inference, the researchers were able to extract
verbatim text from what appeared to be real documents, including code snippets,
private messages, medical records, and legal documents, from several commercial
language model APIs. In many cases, the models could be prompted to reproduce
sensitive content by presenting them with a fragment of the same text as a
prompt.
"The
assumption that data fed into AI training pipelines becomes anonymized and
unrecoverable has proven to be incorrect," said Dr. Priya Nair, a
co-author of the research. "Sensitive information can persist in model
weights and be extracted by anyone with API access and knowledge of the right
prompting techniques."
The findings
have significant implications for organizations that have used AI services to
process sensitive documents, for users whose personal communications may have
been included in training datasets without their knowledge, and for the broader
AI industry's approach to privacy in training data selection and model design.
AI providers
are being called upon to implement stronger technical measures to prevent
training data extraction, including differential privacy techniques during
training and output filtering mechanisms.





Comments